If you’ve reached the point where your clusters won’t stabilize, your supervisor is asking why you chose three groups instead of four, or the SPSS output in front of you doesn’t match anything your literature review prepared you for, you’re not alone. Cluster analysis looks straightforward until you have to defend it: the method choice, the number of clusters, the standardization decision, the interpretation of every group you’ve created. A technically correct run in SPSS is not the same as a defensible one.
We provide SPSS cluster analysis help for dissertation students and researchers who need an experienced statistician to guide method selection, prepare data correctly, evaluate cluster solutions, validate results, and translate SPSS output into a coherent, examiner ready narrative. Whether you’re starting from a blank dataset or already have output you can’t explain, we can help you move forward with confidence.
Send us your research questions and dataset, and we’ll tell you exactly what your cluster analysis needs before you write another word of Chapter 4.
Professional Cluster Analysis Support in SPSS
Help means different things depending on where you are in the process, so our support is built around the actual decision points that trip researchers up rather than a fixed package of deliverables.
We work with you on:
- Research question review, confirming that clustering is actually the right technique for what you’re trying to answer
- Dataset assessment, checking sample size, variable types, and structure against what your chosen method requires
- Variable selection, identifying which variables belong in the analysis and which are diluting it
- Preprocessing, handling missing data, outliers, and scale differences before they distort distance calculations
- Method selection, matching K means, hierarchical, or Two Step clustering to your data and goals
- Cluster number evaluation, comparing candidate solutions using more than a single convenient statistic
- Interpretation, turning cluster centers and profiles into substantive, theory connected groups
- Cluster profiling, describing what distinguishes each cluster in language your committee can use
- Reporting, structuring Chapter 4 (or your results section) so the methodology and findings hold up under scrutiny
- Dissertation revisions, responding to supervisor or examiner feedback on an analysis you’ve already submitted
If you’d rather work through the SPSS menus yourself first, our how to perform cluster analysis in SPSS tutorial walks through the procedure step by step. This page is for what comes before and after that: the decisions the menus don’t make for you.
When Do You Need Help With Cluster Analysis?
Researchers typically contact us at one of these points:
- You know cluster analysis fits your research design but aren’t sure which method suits your variables
- You’ve run K means and gotten a two cluster solution with one cluster containing almost every case
- Your supervisor asked you to justify why you chose four clusters instead of three, and you don’t have a strong answer
- You standardized some variables but not others, and now you’re not sure if that’s affecting your results
- Your dendrogram is dense and hard to read, and you don’t know where to make the cut
- You’ve already written your results section, but an examiner flagged the interpretation as unsupported
- You’re preparing for a viva or defense and need to be able to explain your clustering decisions under questioning
- You ran the analysis correctly but the resulting clusters don’t map onto anything theoretically meaningful
If any of these sound familiar, the issue usually isn’t that SPSS produced the wrong numbers. It’s that the decisions around those numbers haven’t been made or explained yet.
Which SPSS Cluster Analysis Method Should You Use?
Use K means when you have a large sample of continuous variables and a rough idea of how many clusters you expect. Use hierarchical clustering when your sample is small to moderate and you want to explore the cluster structure before committing to a number. Use Two Step clustering when your dataset mixes categorical and continuous variables or is too large for hierarchical methods.
The reasoning behind each choice matters more than the label.
K Means Cluster Analysis
K means partitions cases into a pre specified number of clusters by minimizing within cluster variance around cluster centers. It scales well to large datasets and produces clean, interpretable output, but it requires you to specify the number of clusters in advance, works best with continuous variables, and is sensitive to outliers and to the initial cluster centers used to start the iteration.
Hierarchical Cluster Analysis
Hierarchical clustering builds a nested structure of cluster solutions, visualized through a dendrogram, without requiring you to fix the number of clusters beforehand. It’s well suited to smaller datasets and exploratory work, since you can inspect multiple candidate solutions at once. Its main limitation is scalability. It becomes computationally heavy and visually unreadable with large samples, and early linkage decisions can’t be undone later in the process.
Two Step Cluster Analysis
Two Step clustering handles both categorical and continuous variables in the same model and can suggest an optimal number of clusters automatically using statistical criteria. It’s a practical option for large, mixed type dissertation datasets, though the automatic cluster number suggestion should still be checked against interpretability rather than accepted by default.
K Means vs Hierarchical vs Two Step Cluster Analysis

| Feature | K Means | Hierarchical | Two Step |
|---|---|---|---|
| Data suitability | Continuous variables | Continuous variables (some distance measures allow ordinal or binary) | Mixed categorical and continuous |
| Number of clusters | Must be specified in advance | Determined by inspecting the dendrogram | Can be suggested automatically or set manually |
| Dataset size | Large samples | Small to moderate samples | Large samples, including mixed data types |
| Main output | Final cluster centers, ANOVA table, cluster membership | Agglomeration schedule, dendrogram | Cluster distribution, predictor importance |
| Advantages | Fast, scalable, easy to interpret | Visual, no pre set cluster count, good for exploration | Handles mixed data, suggests solution count |
| Limitations | Sensitive to outliers and starting values, requires pre specified k | Computationally heavy at scale, early decisions are irreversible | Less transparent algorithm, still needs interpretability checks |
| Typical dissertation use | Segmenting a large survey sample into behavioral groups | Exploring structure in a smaller pilot or qualitative adjacent sample | Segmenting mixed demographic and attitudinal data |
Choosing between these isn’t a matter of picking a better method. It’s matching the method’s assumptions to your data and your research question. This is one of the most common places dissertation cluster analyses go wrong, and it’s usually fixable before you run a single case.
Need help deciding which clustering approach fits your research? Send your research questions and dataset for a professional review before you commit to a method.
How We Prepare Data Before Cluster Analysis
Cluster solutions are highly sensitive to how the data going into them was prepared. Two researchers with identical raw data can get materially different clusters based on preprocessing choices alone.
Variable Selection
Including variables that aren’t theoretically relevant can distort distances and pull cases into clusters that don’t make substantive sense. Every variable in the model should have a reason to be there.
Missing Data
Missing values need a documented, defensible handling strategy, such as listwise deletion or imputation, chosen based on how much data is missing and why, not by default settings.
Outliers
A small number of extreme cases can pull cluster centers and create a spurious outlier cluster that has no real interpretive value. Outliers should be identified and addressed before clustering, not explained away afterward.
Standardization
Variables measured on different scales can dominate distance calculations if left untransformed. See the dedicated section below for a full explanation.
Correlated or Redundant Variables
Highly correlated variables effectively get double counted in distance calculations, skewing the solution toward whatever construct those variables represent.
Measurement Scale
Continuous, ordinal, and categorical variables require different distance measures and, in some cases, different clustering procedures altogether.
If your dataset needs broader cleaning beyond what’s specific to clustering, our data cleaning services cover coding, missing value handling, and outlier treatment across a full dataset.
Should Variables Be Standardized Before Cluster Analysis?
This question deserves its own answer because it quietly determines the outcome of the entire analysis.
Cluster analysis groups cases based on distance, and distance calculations are dominated by whichever variable has the largest numeric range, regardless of whether that variable is actually the most important one theoretically.
Consider a dataset with annual income measured in thousands, ranging from roughly 20 to 200, and satisfaction measured on a 1 to 5 scale. Without standardization, a difference of fifty thousand dollars between two cases will overwhelm a full four point difference in satisfaction simply because of the units involved, not because income matters more to the research question. The clustering algorithm has no way of knowing that both variables were meant to carry equal conceptual weight.
Standardizing variables, typically by converting to z scores, puts every variable on a comparable scale so that no single measure mechanically dominates the solution because of how it happens to be coded. Standardization isn’t always automatic, though. In some cases it’s appropriate to leave variables in their natural units, particularly when relative scale genuinely reflects importance. This is a judgment call that should be made deliberately, not skipped.
How Many Clusters Should You Choose?
There is no single statistic that tells you the correct number of clusters, and any source that claims otherwise is oversimplifying. A defensible cluster number decision draws on multiple forms of evidence together.
- The dendrogram, where large jumps in linkage distance can suggest natural break points
- The agglomeration schedule, where abrupt coefficient changes between stages can indicate where clusters stop being meaningfully distinct
- Cluster sizes, since extremely small or extremely unbalanced clusters are often a sign the solution isn’t stable
- Interpretability, because a statistically plausible solution that produces clusters with no coherent substantive meaning isn’t usable
- Stability, checking whether the solution holds up under small changes to the sample, variables, or starting values
- Theory, since your literature review may already suggest an expected number of groups worth testing against the data
- Alternative solutions, comparing two or three candidate cluster counts side by side rather than committing to the first one that runs
The strongest dissertation cluster analysis chapters don’t present a single number and move on. They show that several plausible solutions were compared and explain, with evidence, why the chosen one was retained.
How to Validate a Cluster Solution

Producing a cluster solution is the easy part. Validating it is what separates a defensible dissertation chapter from a set of numbers an examiner can pick apart.
Validation should address:
- Solution stability, whether the clusters hold up when the analysis is re run with different starting values or a resampled subset of cases
- Alternative cluster counts, whether the chosen solution has been compared against at least one plausible alternative
- Substantive interpretability, whether the resulting groups make sense given the theory and context of the research
- Internal consistency, whether cases within a cluster resemble each other more than they resemble cases in other clusters, beyond what the algorithm forces by design
- Sensitivity to variable selection, whether removing or adding a borderline variable meaningfully changes the solution
- Outlier sensitivity, whether the solution depends on a small number of extreme cases
- Replication or split sample checks, whether the same structure emerges in a held out portion of the data where sample size allows
- Cluster separation, whether the clusters are distinct from each other or overlap so much that the grouping adds little value
It’s worth being honest about the limits here too. Cluster analysis is exploratory by nature, internal validation statistics have known weaknesses, and no combination of checks proves a solution is true in an absolute sense. What they can do is show that a solution is reasonable, stable, and defensible, which is what a dissertation committee is actually evaluating.
For broader methodological questions about how your clustering decisions fit into your overall analysis plan, our dissertation statistics consultant service covers guidance beyond clustering specifically.
Understanding SPSS Cluster Analysis Output
SPSS produces several output blocks, and misreading any one of them can lead to an interpretation error that carries through the rest of the chapter.
Cluster Membership
The cluster number assigned to each case. This is the raw material for any further profiling or cross tabulation.
Initial Cluster Centers
The starting points K means uses before iterating. These are useful mainly for understanding how the algorithm began, not for interpretation.
Final Cluster Centers
The mean value of each variable within each final cluster. This is the core table used to describe and name each group.
Distances Between Final Cluster Centers
Shows how far apart cluster centers are from one another, which speaks to how distinct the clusters actually are.
ANOVA Table
This table shows which variables differentiate the clusters most strongly, but it should not be treated as an ordinary independent significance test. Because the clusters were formed specifically to maximize differences on these variables, the p values are descriptive of separation strength rather than a valid hypothesis test in the traditional sense. Reporting them as if they were independent confirmatory tests is one of the most common cluster analysis errors in dissertations.
Dendrogram
A visual tree of how cases and clusters combine at each stage, used in hierarchical clustering to help judge cluster number cut points.
Agglomeration Schedule
The numeric companion to the dendrogram, showing the distance coefficient at each combination stage.
Cluster Sizes
The number of cases in each cluster. This is critical for spotting unstable or degenerate solutions.
Cluster Profiles
The synthesized description of each cluster, usually built from final cluster centers plus any supplementary variables used to characterize the groups.
Common SPSS Cluster Analysis Problems and How We Diagnose Them
| Problem | Likely Issue | What Should Be Checked |
|---|---|---|
| One huge cluster and one tiny cluster | Outliers pulling the solution, or an inappropriate cluster count | Outlier screening, variable scaling, alternative cluster count solutions |
| Clusters change dramatically between runs | Unstable solution | Starting values for K means, variable set, sample composition |
| Dendrogram is difficult to interpret | Weak or ambiguous separation between groups | Agglomeration schedule coefficients, alternative linkage methods |
| One variable dominates the solution | Unstandardized variables on very different scales | Standardization decision, distance measure used |
| Clusters have no meaningful interpretation | Poor variable selection or variables unrelated to the research question | Theoretical relevance of each variable, cluster profile review |
| Two Step suggests an unexpected number of clusters | Automatic criterion conflicting with interpretability | Manual comparison against two or three alternative solutions |
| Results differ from a prior published study | Different variable set, sample, or preprocessing choices | Direct comparison of methodology against the reference study |
Example of Cluster Analysis Interpretation
All figures below are hypothetical and illustrative only.
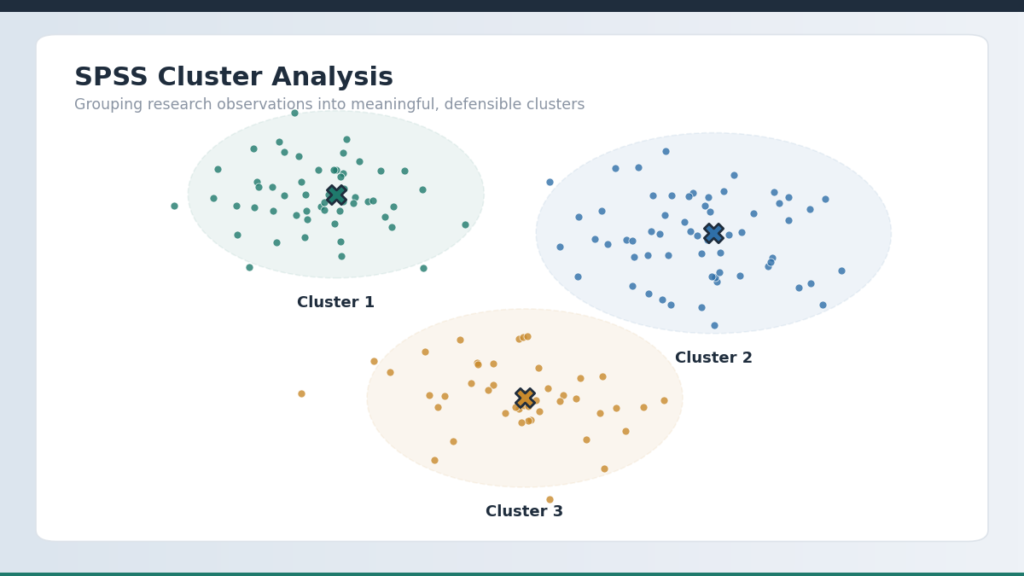
Suppose a researcher is studying student engagement using five variables: attendance, weekly study hours, assignment completion rate, academic confidence, and online engagement. A three cluster K means solution might produce results roughly like this.
Cluster 1, Highly Engaged Students, shows high attendance, high study hours, near complete assignment completion, and high academic confidence. Cluster 2, the Moderate Engagement Group, shows mid range values across all five variables, with no single standout strength or weakness. Cluster 3, Students at Risk of Disengagement, shows low attendance, low assignment completion, and notably low academic confidence relative to the other two groups.
The researcher wouldn’t stop at labeling the groups. They’d check cluster sizes for balance, compare this three cluster solution against a four cluster alternative to confirm three was genuinely the better fit, and connect the at risk cluster’s profile back to the engagement literature to explain why low confidence and low completion tend to co occur. That connective work, not the cluster centers themselves, is what turns SPSS output into an interpretation a committee will accept.
How to Report Cluster Analysis in a Dissertation
A complete cluster analysis write up typically documents the research objective the clustering was meant to address, the variables entered into the analysis and why they were selected, preprocessing steps including how missing data and outliers were handled, whether and how variables were standardized, the clustering algorithm used, the distance measure and linkage method where relevant, the rationale for the final number of clusters, the number of cases in each cluster, cluster profiles describing what distinguishes each group, validation steps taken and their results, and a substantive interpretation connecting the clusters back to the research question.
Here is an illustrative APA style example using hypothetical data:
“A K means cluster analysis was conducted on standardized scores for attendance, weekly study hours, assignment completion, academic confidence, and online engagement (N = 214). Following comparison of two, three, and four cluster solutions, a three cluster solution was retained based on cluster interpretability, size balance, and separation between final cluster centers. Cluster 1 (n = 79) was characterized by high engagement across all indicators; Cluster 2 (n = 96) showed moderate engagement; and Cluster 3 (n = 39) showed low attendance and assignment completion alongside markedly lower academic confidence.”
Cluster Analysis Results Table Example
The table below is a hypothetical, illustrative example only.
| Variable | Cluster 1 (n=79) | Cluster 2 (n=96) | Cluster 3 (n=39) | Interpretation |
|---|---|---|---|---|
| Attendance percent | 92.4 | 78.1 | 54.6 | Sharp drop off in Cluster 3 |
| Weekly study hours | 14.2 | 8.7 | 3.9 | Declines steadily across clusters |
| Assignment completion percent | 96.8 | 81.3 | 47.2 | Cluster 3 well below the others |
| Academic confidence (1 to 5) | 4.3 | 3.4 | 2.1 | Largest gap of any variable |
| Online engagement (1 to 5) | 4.0 | 3.1 | 2.4 | Moderate separation |
Cluster Analysis vs Factor Analysis
Cluster analysis groups observations, or cases, based on similarity across variables. Factor analysis groups variables based on shared underlying dimensions. If your goal is to identify types of respondents, cluster analysis fits. If your goal is to identify the underlying structure behind a set of survey items, factor analysis is the appropriate tool. The two are sometimes used together, with factor analysis reducing variables first and cluster analysis grouping cases second, but they answer fundamentally different questions.
Cluster Analysis vs Regression Analysis
Cluster analysis is a grouping technique with no dependent variable. Regression analysis tests relationships between a dependent variable and one or more predictors. If your research question is whether there are distinct types of respondents in your sample, clustering fits. If your question is whether X predicts Y, you need regression analysis help instead. The two are not interchangeable, and choosing the wrong one at the proposal stage is a common source of major dissertation revisions later.
SPSS Cluster Analysis Help for Dissertation Students
Cluster analysis in a dissertation carries a different burden of proof than cluster analysis in an applied business report. A committee will expect you to defend, in detail, why clustering was the appropriate technique for Chapter 4 or your results section, why your specific variables were selected and how they connect to your literature review, why you chose your clustering method over the alternatives, why your final cluster count is the right one and not just a convenient one, and how you validated the solution rather than accepting the first output SPSS produced.
We help at every stage of this process, from planning before you touch SPSS, through interpreting output you’ve already generated, to responding directly to supervisor or examiner feedback and preparing clear, confident explanations for your defense or viva. If a reviewer has flagged your interpretation as unsupported, we can review exactly what was submitted and identify what needs to change before resubmission.
Already generated your SPSS output? We can review your cluster solution, interpretation, and reporting before you submit your dissertation.
What Our Cluster Analysis Service Includes
| Service | What We Help With |
|---|---|
| Dataset review | Assessing whether your data and sample support clustering |
| Data preparation | Missing values, outliers, coding, and scale checks |
| K means analysis | Setup, cluster count testing, and center interpretation |
| Hierarchical analysis | Linkage method selection and dendrogram interpretation |
| Two Step analysis | Mixed variable clustering and solution evaluation |
| Cluster validation | Stability checks, alternative solution comparison |
| Output interpretation | Reading and explaining every relevant SPSS table |
| Cluster profiling | Naming and describing clusters in substantive terms |
| APA reporting | Drafting a clear, examiner ready results write up |
| Dissertation revisions | Addressing supervisor or examiner feedback directly |
Why Work With an SPSS Cluster Analysis Expert?
The value isn’t in running a procedure you could technically run yourself. It’s in the reasoning behind each decision along the way: why one clustering method fits your data better than another, why a particular variable was excluded, why a four cluster solution was rejected in favor of three, and why the ANOVA table in your output shouldn’t be reported the way a typical significance test would be.
That reasoning is what holds up under supervisor questioning and examiner scrutiny, and it’s what a generic tutorial or automated tool can’t provide, because it depends on your specific dataset, research question, and academic context. We won’t promise a particular grade, outcome, or approval, because no honest statistical consultant can guarantee that. What we can offer is a methodologically sound analysis you can explain and defend on its own merits.
For statistical support beyond clustering specifically, our SPSS statistics help page covers our broader range of services.
Our Cluster Analysis Support Process
- Review your research questions to confirm cluster analysis is the appropriate technique.
- Review your dataset and variables for suitability, scale, and sample size.
- Check preprocessing requirements, including missing data, outliers, and standardization.
- Select an appropriate clustering approach, whether K means, hierarchical, or Two Step.
- Compare and evaluate candidate solutions rather than settling on the first output.
- Interpret and profile the final clusters in terms connected to your research question.
- Prepare reporting and explanations you can use directly in your dissertation and defend if questioned.
Frequently Asked Questions
Cluster analysis is a multivariate technique that groups cases into clusters based on similarity across selected variables, without a predefined dependent variable. SPSS offers three main procedures: K means, hierarchical, and Two Step clustering, each suited to different data types and sample sizes.
It depends on your data and sample size. K means suits large samples of continuous variables when you have an expected cluster count. Hierarchical clustering suits smaller samples and exploratory work. Two Step suits large, mixed categorical and continuous datasets. The right choice should reflect your data’s structure, not convenience.
There’s no single rule. A defensible choice draws on the dendrogram or agglomeration schedule, cluster size balance, interpretability, stability under re testing, and relevant theory, comparing at least two plausible solutions rather than accepting the first one.
Usually yes, when variables are measured on different scales, since unstandardized variables with larger ranges can dominate distance calculations regardless of their actual importance. Whether to standardize should be a deliberate methodological decision, not a default setting.
K means requires you to specify the number of clusters in advance and works efficiently on large samples. Hierarchical clustering builds a nested tree of solutions without requiring a pre set cluster count, which makes it useful for exploration but harder to scale to large datasets.
Standard K means and hierarchical clustering are built primarily for continuous variables, though certain distance measures allow some categorical or ordinal data. Two Step clustering is generally the better option when your dataset genuinely mixes categorical and continuous variables.
A dendrogram shows how cases and clusters combine at increasing distances. Larger jumps in linkage distance between stages often mark a reasonable point to cut the tree into a specific number of clusters, though this should be checked against the agglomeration schedule and interpretability, not read visually alone.
Validation involves checking solution stability, comparing alternative cluster counts, confirming substantive interpretability, testing sensitivity to variable selection and outliers, and, where sample size allows, checking replication in a held out subsample.
A complete report documents the research objective, variables used, preprocessing steps, the clustering method and distance or linkage measures, the rationale for the final cluster count, cluster sizes and profiles, validation results, and a substantive interpretation connecting the clusters back to the research question.
Yes. We regularly review completed analyses, checking method choice, preprocessing, cluster count justification, and interpretation, and help revise the results section in response to supervisor or examiner feedback.
Get Expert SPSS Cluster Analysis Help
Whether you haven’t opened SPSS yet, you’re staring at output you can’t fully explain, or you’ve received feedback that your cluster solution isn’t justified, the underlying problem is usually the same. A defensible cluster analysis requires more decisions than the software makes visible.
Send us your research questions, dataset, or existing SPSS output, and we’ll help you build a cluster analysis you can explain, defend, and submit with confidence.