Dissertation data analysis support that fits real research work
Dissertation data analysis help takes you from a raw dataset to results you can explain and defend. Our statisticians prepare your data, choose and run the right tests, check every assumption and report the findings in APA 7 format, working in SPSS, R, Stata, Python or Excel. You get the analysis plus a clear explanation of what each result means for your research questions.
Most students reach this stage with data in hand and a list of open questions. How do I clean this file? Which test fits my hypotheses? What do I do when normality fails? How do I turn this output into Chapter 4? This page answers those questions and shows exactly how we work, including a complete worked example from raw survey file to written results.
At a glance
| Question | Answer |
|---|---|
| Who it is for | Master’s, PhD, DBA, EdD, DNP and PsyD students with quantitative or mixed-methods data |
| What we do | Data preparation, test selection, assumption checks, analysis, interpretation, APA 7 reporting, revisions |
| Software | SPSS, R, Stata, Python, Excel, Jamovi, Minitab |
| What you get | Cleaned data, output with syntax or code, APA tables, results narrative, test justification notes |
| Pricing | Free fixed-price quote; pay only after you approve it |
Request a Free Quote · Fixed-price quote · Pay only after you approve it · Confidential
On this page
- What dissertation data analysis help includes
- Choosing the right analysis method
- Data preparation checklist
- Worked example: survey data to APA results
- Software we use
- Process and what you receive
- Pricing and turnaround
- FAQ
What Dissertation Data Analysis Help Includes
Good analysis is a sequence of decisions made in the right order. One weak step, such as a miscoded variable or an unchecked assumption, carries through to everything after it. We cover each stage, or only the stages you need.
| Stage | What we do | Why it matters |
|---|---|---|
| 1. Study review | Read your research questions, hypotheses, variables and methods chapter | The analysis must answer the questions you set, not different ones |
| 2. Data preparation | Check coding, handle missing data, reverse-score items, screen outliers, build scale scores | Errors here produce wrong results that look right |
| 3. Method selection | Match each hypothesis to a test based on design and measurement level | Choosing the wrong test is a frequent examiner criticism |
| 4. Assumption testing | Normality, homogeneity, linearity, independence, multicollinearity | A test is only valid if its assumptions hold or are handled |
| 5. Analysis | Descriptive, inferential and multivariate tests in your chosen software | Accurate, reproducible results with syntax or code |
| 6. Interpretation | Explain direction, size and meaning of every result | Output alone does not answer a research question |
| 7. Reporting | APA 7 tables, figures and a results narrative | A clear Chapter 4 that follows your research questions |
| 8. Revisions | Update the analysis after supervisor or committee feedback | Feedback is addressed point by point |
You can bring us in at any stage. Some students send a raw survey export. Others already have output and need it checked, interpreted or written up. If your analysis is done and you mainly need the write-up, see our Chapter 4 dissertation help.
Choosing the Right Analysis Method
The right test depends on three things: what your research question asks (difference, relationship or prediction), how your variables are measured and how your groups or observations are structured. Use this table as a starting point.
| Research question asks | Variables | Parametric test | If assumptions fail |
|---|---|---|---|
| Do two independent groups differ? | Continuous outcome, 2 groups | Independent-samples t-test | Mann-Whitney U |
| Did scores change from pre to post? | Same people measured twice | Paired-samples t-test | Wilcoxon signed-rank |
| Do three or more groups differ? | Continuous outcome, 3+ groups | One-way ANOVA | Kruskal-Wallis |
| Do groups differ over time? | Repeated measures plus groups | Mixed ANOVA or linear mixed model | Robust or non-parametric alternatives |
| Do groups differ after controlling for a covariate? | Continuous outcome and covariate | ANCOVA | Robust regression |
| Are two categorical variables related? | Two categorical variables | Chi-square test of independence | Fisher’s exact test |
| Are two continuous variables related? | Two continuous variables | Pearson correlation | Spearman correlation |
| Do several variables predict an outcome? | Continuous outcome, several predictors | Multiple regression | Robust standard errors or bootstrapping |
| What predicts a yes/no outcome? | Binary outcome | Binary logistic regression | Penalized or exact logistic regression |
| Does a scale measure what it should? | Scale items | Reliability analysis and confirmatory factor analysis | Alternative estimators for ordinal items |
Real studies are rarely this tidy. Likert data, small samples, unequal groups and nested data (students within schools, patients within clinics) all change the decision. Your statistician explains the choice in writing so you can justify it in your methods chapter. For group comparisons in detail, see our ANOVA help and two-way ANOVA help pages.
Data Preparation Checklist
Data preparation is the most overlooked part of dissertation analysis. Before any test is run, your statistician works through this checklist and records every change in a data log.
- Variable view set up: names, labels, value labels and measurement levels defined
- Coding checked: out-of-range values (such as a 7 on a 5-point scale) found and corrected
- Duplicates and test responses removed: repeated IDs, survey previews and incomplete attention checks
- Missing data assessed: amount and pattern reviewed, then handled by a justified rule such as exclusion above a threshold, proration or multiple imputation
- Reverse-worded items recoded: before any scale scores are built
- Reliability checked: Cronbach’s alpha (or omega) for each scale
- Scale scores computed: mean or sum scores created as your instrument’s manual specifies
- Outliers screened: z-scores, boxplots and, for regression, Mahalanobis and Cook’s distance
- Distributions inspected: histograms, skewness and kurtosis for each key variable
A clean, documented dataset makes every later step faster and much easier to defend. It also means your supervisor can see exactly what was done to the data and why. For survey projects in particular, see our online survey experts page.
Worked Example: From Raw Survey Data to APA Results
Illustrative example using a simulated dataset. The numbers were calculated from that dataset and are internally consistent, but they do not come from a real study.
Research question: Do workload and social support predict burnout among nurses, after controlling for years of experience?
Hypotheses: H1: Higher workload predicts higher burnout. H2: Higher social support predicts lower burnout.
Step 1: Prepare the data
- 196 surveys were returned. 8 respondents left more than 20% of items blank and were excluded, leaving N = 188.
- The remaining 49 missing item responses (1.6% of item data) were handled by computing each scale score as the mean of the items answered.
- One reverse-worded social support item was recoded before scoring.
- Reliability was good for all scales: workload α = .83, social support α = .86, burnout α = .86.
Step 2: Describe the variables
| Variable | M | SD | 1 | 2 | 3 |
|---|---|---|---|---|---|
| 1. Years of experience | 6.91 | 4.65 | — | ||
| 2. Workload | 2.88 | 0.84 | .09 | — | |
| 3. Social support | 2.99 | 0.89 | −.07 | −.26** | — |
| 4. Burnout | 2.94 | 0.80 | .03 | .47** | −.42** |
Note. N = 188. Scale scores range from 1 to 5. ** p < .001.
Step 3: Choose the test and check assumptions
The question asks whether two predictors explain burnout beyond a control variable, so a hierarchical multiple regression fits: experience in Step 1, workload and social support in Step 2.
| Assumption | Check | Result |
|---|---|---|
| Multicollinearity | Variance inflation factor (VIF) | All VIFs ≤ 1.08 |
| Independence of residuals | Durbin-Watson | 1.97 |
| Normality of residuals | Shapiro-Wilk, Q-Q plot | W = .995, p = .787 |
| Linearity and homoscedasticity | Residual plot, Breusch-Pagan, RESET | BP p = .965; RESET p = .662 |
Step 4: Run the analysis
| Predictor | B | SE | β | t | p | 95% CI for B |
|---|---|---|---|---|---|---|
| Constant | 2.77 | 0.29 | 9.66 | < .001 | [2.21, 3.34] | |
| Years of experience | −0.005 | 0.011 | −.03 | −0.46 | .649 | [−0.03, 0.02] |
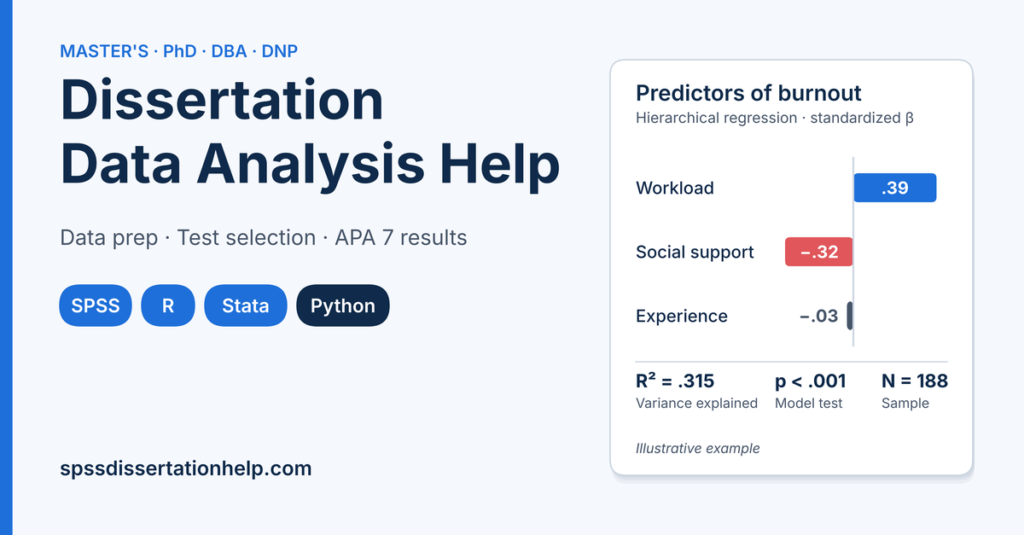
| Workload | 0.37 | 0.06 | .39 | 6.10 | < .001 | [0.25, 0.49] |
| Social support | −0.29 | 0.06 | −.32 | −5.11 | < .001 | [−0.41, −0.18] |
Note. Final model (Step 2). R² = .315, adjusted R² = .304.
Step 5: Write the results
A hierarchical multiple regression examined whether workload and social support predicted burnout after controlling for years of experience. Experience alone did not predict burnout, R² = .001, F(1, 186) = 0.18, p = .669. Adding workload and social support significantly improved the model, ΔR² = .314, F(2, 184) = 42.25, p < .001, and the final model explained 31.5% of the variance in burnout, F(3, 184) = 28.26, p < .001. Higher workload predicted higher burnout, β = .39, t(184) = 6.10, p < .001, supporting H1. Higher social support predicted lower burnout, β = −.32, t(184) = −5.11, p < .001, supporting H2.
That is the standard we work to on every project: documented preparation, a justified test, reported assumption checks, accurate tables and a narrative tied to each hypothesis.
Common Data Analysis Mistakes We Fix
These common problems in dissertation analyses can each lead to revision requests. Here is how we fix them:
| Mistake | Why it is a problem | The fix |
|---|---|---|
| Reverse-worded items not recoded | Scale scores are wrong and reliability drops | Recode before scoring, then recheck alpha |
| Several t-tests instead of one ANOVA | Inflates the chance of a false positive | One-way ANOVA with post hoc tests |
| Reporting p-values only | Readers cannot judge the size of an effect | Add effect sizes and confidence intervals |
| Assumptions skipped | The test may not be valid for your data | Test, report, and use a justified alternative if needed |
| Missing data ignored or deleted without a rule | Smaller sample and possible bias | Assess the pattern, then apply and report a clear rule |
| “Non-significant” read as “no effect” | Overstates what the data shows | Report the estimate, interval and power limitations |
| Correlation described as causation | Examiners will challenge the conclusion | Use relationship language unless the design is experimental |
| Numbers in the text do not match the output | Damages examiner confidence | Cross-check every statistic against the output |
How to Structure Your Results Chapter (Chapter 4)
| Section | What it contains |
|---|---|
| Introduction | A short reminder of the research questions and the order of the analyses |
| Data preparation | Response rate, exclusions, missing data handling, recoding and outliers |
| Sample description | Demographics and descriptive statistics for key variables |
| Reliability | Cronbach’s alpha or other reliability evidence for each scale |
| Assumption checks | What was tested, the results and how any violations were handled |
| Results by research question | One subsection per question or hypothesis, with test, table and narrative |
| Additional analyses | Post hoc tests, sensitivity or robustness checks |
| Summary | Which hypotheses were supported and which were not, without discussion |
Keep interpretation and comparison with the literature for your discussion chapter. Chapter 4 reports what the data shows.
Software We Use for Dissertation Data Analysis
We work in whichever software your university, supervisor or field expects. Every delivery includes the syntax or code, so your results can be reproduced and checked.
| Software | Typical dissertation use |
|---|---|
| SPSS | Surveys, group comparisons and regression in psychology, education, nursing and business; PROCESS macro for mediation and moderation |
| R | Advanced and reproducible modeling, mixed models, publication-quality graphs. See data analysis in R |
| Stata | Panel data, econometrics and epidemiology in economics, finance and public health |
| Python | Large or messy datasets, automation and data preparation (pandas, SciPy) |
| Excel | Early data cleaning, simple summaries and charts |
| Jamovi and Minitab | Student-friendly alternatives when a course requires them. See how to use Jamovi for data analysis and Minitab help |
If your dissertation is SPSS-based from start to finish, our main SPSS dissertation help service covers the whole project.
Support by Discipline and Dissertation Stage
By discipline
| Field | Typical data and methods |
|---|---|
| Psychology | Validated scales, group differences, regression, mediation and moderation. See psychology dissertation help |
| Education | Surveys, pre/post designs, ANCOVA, nested data such as students within schools |
| Nursing and public health | Patient outcomes, logistic regression, survival analysis, clinical relevance of effects |
| Business and management | Customer and employee surveys, regression, factor analysis, structural models |
| Social sciences | Large secondary datasets, weighting, cross-sectional analysis, multivariate regression |
| Economics and finance | Time series, panel data, econometric diagnostics |
By dissertation stage
- Data just collected: full preparation, analysis and reporting
- Analysis started but stuck: we pick up from your current file and output
- Output done, interpretation unclear: we check the tests and explain the results
- Supervisor or committee feedback: we re-run what is needed and document each change
The same standard applies at every degree level, adjusted to what your examiners expect. Master’s projects need correct standard tests clearly reported. Doctoral projects often need stronger justification, robustness checks and advanced models such as multivariate analysis or repeated measures ANOVA.
Who You Work With and How It Works
Your project is handled by a named statistician matched to your field and method. Our team includes PhD-level statisticians and Master’s-level quantitative researchers, among them:
- Dr. Andrea James, PhD in Educational Research: more than eight years guiding SPSS dissertations, specializing in survey data, scale validation, factor analysis and regression.
- Jay Spankston, MSc in Applied Statistics: SPSS and research methods consultant who explains complex tests in plain language and delivers clean, well-labelled output and syntax.
Meet the wider team on our statisticians page and read client feedback on our reviews page.
How it works
- Send your project. Submit your details: research questions, methods chapter, dataset, any feedback and your deadline.
- Get a fixed-price quote. We confirm the analysis needed and send a quote with a realistic timeline.
- Approve and pay securely. You pay only after approving the quote (Visa, Mastercard, PayPal or M-Pesa).
- Analysis and reporting. Your statistician prepares the data, runs the tests and writes up the results.
- Review and questions. Ask anything by email or WhatsApp, or book a screen-share walkthrough.
- Revisions. If your supervisor requests changes, the same statistician makes them.
What you receive
- Cleaned dataset and a data preparation log
- Output files plus syntax or code
- Assumption-check summary
- APA 7 tables and figures
- Results narrative organized by research question
- Notes explaining why each test was chosen
Which service fits you?
This page covers the full analysis stage across software. If you want guidance while you run the analysis yourself, work with a dissertation statistics consultant. If you want a dedicated expert for your whole project, you can hire a statistician for your dissertation.
Typical projects we support
| Student | Design | Support provided |
|---|---|---|
| Master’s, Education | Survey with about 200 respondents | Test selection, SPSS analysis and results write-up |
| PhD, Nursing | Pre-post intervention study | Full review and re-analysis after supervisor feedback |
| MBA, Business | Correlational survey | SPSS analysis and reporting for a working professional |
| Master’s, Psychology | Experimental design | SPSS analysis plus viva preparation notes |
Read what students say about working with us on our reviews page.
How to Choose a Dissertation Data Analysis Service
Many sites offer dissertation data analysis help. Before you share your data or pay anyone, check these points:
| Check | What a good service shows you | Red flag |
|---|---|---|
| Who does the work | Named statisticians with stated qualifications | Anonymous “experts” with no credentials |
| Method justification | A written reason for each test | Output with no explanation |
| Reproducibility | Syntax or code with every delivery | Results you cannot re-run |
| Assumption checks | Reported tests and how violations were handled | No mention of assumptions |
| Reporting standard | Correct APA 7 tables and notation | Pasted software output |
| Revisions | Supervisor feedback addressed by the same analyst | Extra fees for every change |
| Price clarity | A fixed quote before you pay | Price changes after delivery |
| Academic integrity | Clear rules on authorship and data | Promises to “guarantee” a grade or results |
The worked example above shows the standard you should expect from any service, including ours.
Ethics, Confidentiality, Pricing and Turnaround
Academic integrity
Statistical analysis support is a widely used form of methodological help, and many universities run statistics consulting services of their own. Policies vary, so check your institution’s rules and keep your supervisor informed. You provide the research questions, design and data, you review everything we deliver, and you remain the author of your dissertation. We never fabricate or alter data to reach significance, and we never reuse another student’s dataset or results.
Confidentiality
Your data, drafts and project details are used only for your project and are never shared with third parties. If your ethics approval sets data-handling conditions, send them with your order and we will follow them. See our privacy policy.
Pricing
Each project receives a free, fixed-price quote. The price depends on your degree level, the number of research questions, the type of analysis, the software, the condition of your dataset and your deadline. You pay only after approving the quote. See our prices for more information.
Turnaround
Timelines depend on the size of the analysis and how ready your data is. Your quote includes a realistic delivery date. If your deadline is close, tell us when you order and we will confirm upfront whether it can be met.
Specialist Analysis Services and Guides
Choose the page that matches your method, software or location.
Statistical methods
- SPSS cluster analysis help
- Binomial test in SPSS help
- SPSS consulting services
- SPSS statistics help
- Online SPSS help
R support
Dissertation and thesis support
By location
- Dissertation data analysis help in Australia
- SPSS dissertation help in Australia
- SPSS dissertation help in Canada
Frequently Asked Questions
It is expert support with preparing your dataset, choosing the right statistical tests, checking assumptions, running the analysis, interpreting the findings and reporting them in your results chapter.
Yes. We recode reverse-worded items, check reliability, build scale scores and choose tests that suit how your survey items are measured.
No. We also work in R, Stata, Python, Excel, Jamovi and Minitab. We use whichever software your university or supervisor requires and include the syntax or code.
Yes. Send your data file, output and draft results. We check whether the tests fit your design, whether assumptions were handled and whether the interpretation is accurate.
Yes. We report findings in APA 7 format, organized by research question. If you only need the write-up, see our Chapter 4 dissertation help page.
We report the violation and handle it with a justified alternative, such as a non-parametric test, a transformation, robust standard errors or bootstrapping.
Yes. We address each comment, re-run what is needed and list the changes so you can respond clearly.
Yes. Your files are used only for your project and are never shared with third parties.
It depends on the size of the analysis and how ready your data is. Your quote includes a realistic delivery date.
Each project gets a free, fixed-price quote based on degree level, research questions, analysis type, software and deadline. You pay only after approving it.
Get Dissertation Data Analysis Help Today
If your data is collected and the next step is unclear, a free quote is the quickest way forward. Send us your research questions, methods chapter, dataset and deadline, and we will confirm the analysis you need and send a fixed-price quote with a realistic timeline.
For the most accurate quote, include:
- your degree level and discipline
- your research questions or hypotheses
- your methods chapter, if available
- your dataset or a description of it
- any supervisor or committee feedback
- your deadline
Want to know more first? Read how it works or contact us.